Test Impact Analysis Explained: How to Run Only the Tests That Matter
Every engineering team eventually hits the same wall: the test suite got big, the suite got slow, and now every pull request waits twenty or thirty minutes for a full regression run that mostly re-verifies untouched code. Developers start skipping tests, merging on green-from-a-subset anyway, or simply ignoring red builds that are "probably flaky." The suite meant to make delivery safe becomes the thing that slows delivery down.
Test impact analysis (TIA) is the discipline of answering one precise question for every change: which tests can this change possibly break? Instead of running everything, you compute a mapping from changed lines and files to the tests that execute them, and you run that subset first — often in seconds — before deciding whether a broader run is warranted.
This guide explains how test impact analysis works, the architectures teams use to build it, how it differs from related practices such as test selection and test prioritization, what a practical implementation looks like in CI, and where the technique can quietly mislead you if you set it up carelessly.
Table of Contents
- What Test Impact Analysis Actually Means
- Why Full Test Suites Stop Scaling
- Core Concepts: Coverage, Mapping, and Selection
- How the Pipeline Works
- Architecture Options: Build Systems vs. Runtime Tooling vs. SaaS
- A Practical CI Walkthrough
- Real-World Example: Cutting a 40-Minute Suite to 4 Minutes
- Common Pitfalls and How to Avoid Them
- TIA vs. Related Practices
- Key Takeaways
- Frequently Asked Questions
- Related Articles
What Test Impact Analysis Actually Means
Test impact analysis is the process of relating changes in source code to tests that depend on that code, and using that relationship to decide what to execute after a change. The "impact" in the name is literal: the analysis computes which tests are impacted by a diff.
At its core, TIA maintains a data structure that records, for each test, the set of production code elements (files, classes, functions, or line ranges) that the test touched during a previous run. When a new commit arrives, the system diffs the code against the base revision, looks up the impacted tests, and produces a subset to run.
Important: TIA does not replace a full regression run forever. Most teams use it as a fast inner loop — a high-signal subset on every push, with a complete suite run nightly or on release branches. Think of it as triage, not as a verdict.
The technique is not new. Research on regression test selection dates back decades, and large build systems have shipped variants of it for years. What changed recently is that ordinary application teams can now adopt it without building a compiler: coverage providers, runtime profilers, and CI platforms all expose enough data to make the mapping practical.
Why Full Test Suites Stop Scaling
Three forces make untargeted test runs increasingly expensive:
- Suite growth outpaces team growth. Tests accumulate with every feature; nobody deletes them. A suite that once took 3 minutes crosses 15, then 40.
- Feedback loops gate merging. If CI is the merge gate, suite latency is directly developer latency. A 40-minute suite with an average wait of 20 minutes compounds across dozens of daily pull requests.
- Most changes are local. A typo fix in a billing formatter does not plausibly break the search ranking tests. Running the whole suite for local changes spends compute and patience proving very little.
The economics are simple: the cost of running everything grows linearly with suite size, while the information value of each additional test run shrinks because the change itself is small.
Core Concepts: Coverage, Mapping, and Selection
The impact map
The central artifact is an impact map: a relation between tests and the code they exercise. Formally, for each test t, store coverage(t) = {code elements touched when t ran}. When a change set Δ arrives, the impacted set is:
impacted(Δ) = { t | coverage(t) ∩ Δ ≠ ∅ }
In practice the granularity is a choice with real trade-offs:
| Granularity | Precision | Overhead | Typical use |
|---|---|---|---|
| File / module level | Low — many false positives | Very low | Monorepos, quick start |
| Function / class level | Medium | Low | Most application suites |
| Line / statement level | High | Higher (storage + diffing) | Large suites where minutes matter |
Building the map
The map is produced by observing test runs, not by reading code statically. Common sources of signal:
- Coverage instrumentation — line or branch coverage per test (
--cov-context=testin pytest, JaCoCo'stestsession context in JVM projects, V8 coverage snapshots). - Build-system dependency graphs — systems like Bazel or Buck2 already know which targets a test depends on, so impact analysis falls out of the graph almost for free.
- Runtime traces — profiling which modules, endpoints, or queries a test touched, useful when the unit of change is a service rather than a file.
Selecting and ranking
Once you have the impacted set, you still decide what order to run and how much to run. This is where selection (what to run) meets prioritization (what to run first). Ranking impacted tests by historical failure rate or recent change frequency is a cheap way to surface the most likely breakages at the top of the report.
How the Pipeline Works
A complete test impact analysis loop has five stages: change detection, map lookup, subset selection, execution, and feedback (where results update the map for next time).
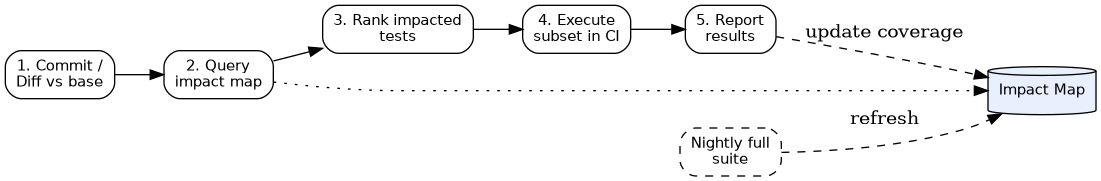
Two details deserve emphasis:
- The map must be refreshed continuously. Coverage recorded three months ago reflects code that may no longer exist. Teams either update the map on every main-branch run or invalidate stale entries automatically.
- The diff base matters. Comparing against the wrong baseline (e.g., an outdated main branch) silently drops impacted tests. Always diff against the exact commit you are merging into.
Architecture Options: Build Systems vs. Runtime Tooling vs. SaaS
There is no single correct implementation. Three broad approaches exist:
1. Build-system-native selection
If your repository is a Bazel or Buck2 monorepo, the build graph already encodes test-to-source dependencies. Changing //payments:ledger automatically reruns only dependent test targets. This is the most precise and lowest-overhead path — but it requires adopting that build system, which most teams cannot do retroactively.
2. Runtime coverage-driven selection
For suites in languages like Python, JavaScript, Java, or Go, you collect per-test coverage during normal runs and persist it as the impact map. On each CI run you:
- Parse the diff to get changed files/functions.
- Query the map for tests whose recorded coverage intersects the diff.
- Run that subset, then run the rest opportunistically (on a schedule, on-demand, or in a background shadow lane).
Tools and features in this space include pytest plugins that report coverage per test, Jest's --changedSince and related affected-project detection, nx affected for JavaScript monorepos, Gradle/JaCoCo test-level contexts on the JVM, and language-agnostic services that ingest coverage from your existing CI.
3. Hosted impact-analysis services
Several commercial platforms ingest your git history and coverage files, maintain the map centrally, and annotate pull requests with "tests likely affected by this change." They add setup convenience and cross-repo visibility, at the cost of sending coverage data to a third party — a consideration worth weighing if your coverage profiles reveal sensitive structural details.
A Practical CI Walkthrough
The following sketch shows a coverage-driven subset inside a generic CI pipeline. Adapt the commands to your stack; the shape of the pipeline is what matters.
# excerpt of a CI job demonstrating impact-based selection
steps:
  - name: Checkout with full history
    run: git fetch origin main --depth=50

  - name: Compute changed files
    run: git diff --name-only origin/main...HEAD > changed.txt

  - name: Restore impact map
    run: |
      curl -sf -o impact-map.json \
        "$IMPACT_MAP_URL" || echo '{}' > impact-map.json

  - name: Select impacted tests
    run: |
      python tools/select_tests.py \
        --diff-base origin/main \
        --map impact-map.json \
        --out selected.txt

  - name: Run impacted subset
    run: pytest $(cat selected.txt | tr '\n' ' ') --cov-context=test

  - name: Upload refreshed map
    run: |
      python tools/merge_map.py --old impact-map.json --new coverage.json
      # upload to your artifact store
A few practical rules of thumb from teams running this in production:
- Fail closed on ambiguity. If the selector cannot parse the diff, if the map is missing for a file, or if a changed file matches no test at all, run the full suite (or at least a broad smoke tier) rather than an empty subset. An empty run is green by accident, which is the worst kind of green.
- Keep a tiered strategy. Tier 1: impacted subset on every push. Tier 2: full suite nightly and on release branches. Tier 3: pre-merge for high-risk paths such as auth, payments, or migrations.
- Publish the subset in the PR report. Developers should see why 12 tests were chosen instead of 2,400. Transparency converts skepticism into trust.
Real-World Example: Cutting a 40-Minute Suite to 4 Minutes
Consider a mid-size SaaS product with a Python backend, a React front end, and roughly 3,200 tests running 40 minutes on every pull request. Median change touches fewer than five files.
Before TIA: every PR waits the full 40 minutes. Developers batch unrelated changes into one PR to amortize the wait — which makes reviews bigger and failures harder to localize.
After TIA:
- Per-test coverage is collected during nightly full runs and merged into the impact map.
- PRs run the impacted subset first — typically 60–150 tests, completing in 3–5 minutes.
- If the subset is green and the diff touches no high-risk area, the PR is mergeable; the full suite continues in the background and reports later.
- Nightly runs refresh the map and catch anything the subset could not see.
Observed effects in setups like this one are consistent across reports: drastically shorter median feedback time, higher merge frequency, and — counter-intuitively for skeptics — better defect detection on the changed code, because developers rerun the subset repeatedly while iterating instead of running it once per day.
Caution: the safety of a subset depends entirely on map freshness and diff correctness. If nightly full runs stop, the map decays, and after a few weeks the subset quietly stops covering what it claims to cover. Treat map refresh as part of your reliability budget, not as a nice-to-have.
Common Pitfalls and How to Avoid Them
- Treating the subset as the whole truth. Emergent failures — integration drift, timing issues, shared-fixture interactions — may involve tests that touch none of the changed lines directly. Keep a full-suite lane.
- Ignoring non-code inputs. Dependency bumps, feature-flag flips, configuration changes, and database migrations alter behavior without changing the lines your map tracks. Classify these as "always full run" or map them explicitly.
- File-level granularity in a monolith. If one 10,000-line file contains everything, file-level impact selects nearly the entire suite. Finer granularity or refactoring into modules restores selectivity.
- Flaky tests poisoning the signal. An impacted subset that includes a known-flaky test produces noisy results and erodes trust. Quarantine flakiness first — see our earlier coverage of flaky test elimination.
- No ownership of the tooling. The selector, the map schema, and the CI glue are production infrastructure. Assign an owner; unowned test tooling rots within a quarter.
TIA vs. Related Practices
These terms get used interchangeably, but they solve different parts of the problem:
| Practice | Question it answers | Typical technique |
|---|---|---|
| Test impact analysis | Which tests depend on this change? | Coverage map ∩ diff |
| Regression test selection (academic) | Which tests may observe a behavioral change? | Static/dynamic analysis of program changes |
| Test prioritization | In what order should tests run? | Historical failure rate, churn, risk scores |
| Test parallelization | How do we run tests faster? | Sharding across machines |
| Test trimming / pruning | Which tests are redundant forever? | Coverage overlap, mutation-based analysis |
TIA and prioritization compose well: select first, then order the selection by risk. Parallelization is orthogonal and complements everything above. Pruning changes the suite itself rather than choosing a subset for a given change.
Key Takeaways
- Test impact analysis maps each change to the tests that actually exercise the affected code, turning a 40-minute suite into a minutes-long inner loop.
- The core artifact is an impact map built from per-test coverage (or a build graph), and it must be refreshed continuously or it silently rots.
- Selection is not a replacement for full regression: keep tiered runs — subset per push, full suite nightly and for high-risk changes.
- Fail closed: missing map entries, unparsable diffs, and dependency or config changes should trigger a broader run, not an empty subset.
- Transparency matters — show developers which tests ran and why, and pair selection with prioritization by risk and historical failure data.
- The technique composes with parallelization and flaky-test quarantine; it does not substitute for them.
Frequently Asked Questions
Is test impact analysis the same as running only changed tests? Not exactly. Running "changed tests" usually means re-running tests near changed files. TIA uses an observed mapping from actual executions — coverage or dependency graphs — so it captures indirect relationships such as a shared utility pulled in by a test in a different directory.
What happens when the impact map is empty or stale? Any robust implementation treats that as a signal to broaden, not to skip. If no tests match a change, that is suspicious: either the change is genuinely untested (itself worth reporting) or the map is out of date. Both outcomes should trigger a wider run or an explicit warning on the pull request.
Does TIA work for end-to-end and UI tests? Less precisely. E2E suites touch many modules at once, so their coverage entries are broad and selection gains shrink. TIA pays off most for unit and integration suites; for E2E, prioritization (running the riskiest journeys first) usually delivers more value than selection.
Do we need a special build system to adopt this?
No. Build-graph-native selection (Bazel, Nx, Turborepo affected projects) is the cleanest path, but coverage-driven selection works with ordinary test runners and a CI job that computes a diff. Teams typically start with file-level granularity using nothing more than git diff and stored coverage files.
How often should the impact map be rebuilt? Refresh it whenever the full suite runs — nightly in most setups — and invalidate entries for files that no longer exist on every merge. If your full runs are rare, cap map age (for example, seven days) and force a rebuild after that.
Related Articles
- Flaky Tests Explained: A Practical Guide to Finding and Eliminating Test Unreliability
- Shift-Left Testing: Integrating Quality Earlier in the Software Development Lifecycle
- Property-Based Testing Explained: Finding Bugs Your Example-Based Tests Will Never Catch
- Mutation Testing Explained: How Breaking Your Code Proves Your Tests Actually Work
- Performance Testing Masterclass — Load, Stress, and Scalability with k6


Comments
Post a Comment