Structured Outputs Explained - Turning Unreliable LLM Text into Valid JSON
Large language models are brilliant at producing text and surprisingly bad at producing data. Ask a model for a JSON object in a production pipeline and you will eventually get prose around the braces, a markdown fence that no strict parser accepts, a hallucinated enum value, or a response truncated mid-string because the token budget ran out. Every one of those failures turns into a retry loop, a support ticket, or a silent data-quality bug downstream.
Structured output techniques solve this by treating the model's response as a constrained generation problem instead of a prompting problem. Instead of asking nicely for JSON, you make every token that would break the schema literally unrepresentable during sampling. The result is output that is valid by construction rather than valid by hope.
This article explains how that works from the tokenizer up, compares the main approaches on the market, walks through a realistic extraction pipeline in Python, and covers the performance trade-offs and pitfalls teams hit in production.
Table of Contents
- Why Free-Form Text Breaks Production Pipelines
- Core Concepts - Schema, JSON Mode, and Tool Calling
- How Constrained Decoding Works
- Grammars, Regular Expressions, and JSON Schema
- The Tooling Landscape
- Real-World Example - An Invoice Extraction Pipeline
- Performance, Cost, and Latency
- Pitfalls and Cautions
- A Practical Checklist
Why Free-Form Text Breaks Production Pipelines
When an LLM answers "extract the fields," you are asking a next-token predictor to simultaneously satisfy a data contract. The model's training optimized it for fluent, helpful text, not for byte-exact serialization. Common failure modes include:
- Wrapper text —
Here is the JSON you asked for:before the actual object. - Markdown fencing — triple backticks around valid JSON that strict parsers reject.
- Invalid escapes — literal newlines inside JSON strings, unescaped quotes in addresses.
- Truncated output — a
max_tokenslimit that cuts the object in half. - Enum drift —
"priority": "urgent"when your schema only allowslow | medium | high. - Type confusion —
"amount": "42.50"as a string where a number is required. - Omitted or hallucinated fields — keys missing entirely, or keys your schema never declared.
The traditional defense is prompt engineering plus try/except retries. That works in a demo and erodes in production: each retry costs latency and tokens, and a model that is mostly reliable still fails often enough to matter at volume.
Important: Validation after generation tells you the output is broken. Constraint during generation prevents it from ever being broken. Both belong in a serious pipeline, but they solve different problems — never ship with validation alone and assume retries will absorb the rest.
Core Concepts - Schema, JSON Mode, and Tool Calling
The terminology around this feature is muddled because every provider brands it differently. It helps to separate four distinct mechanisms:
| Mechanism | What it constrains | Guarantee | Typical use |
|---|---|---|---|
| Prompt-only ("return JSON") | Nothing enforceable | None — output may not parse | Prototypes |
| JSON mode | Token choices limited to JSON-valid sequences | Syntactically valid JSON, any shape | Loose extraction |
| Structured outputs / guided decoding | Token choices limited to a compiled JSON Schema | Valid JSON matching the schema | Production extraction, agents |
| Tool / function calling | Response shaped as a tool invocation | Well-formed call, argument validity varies | Agent tool use |
JSON Schema is the shared contract language. It describes objects, required keys, types, enums, arrays, numeric bounds, and nesting. Almost every structured-output feature in modern inference stacks accepts a JSON Schema (or a subset of it) as input.
Tool calling looks similar but is a different animal: the model decides whether to call a tool and with what arguments, whereas structured outputs force the entire response into a schema. Many APIs let you supply a schema to a tool's parameters and then constrain decoding against that schema too — the combination is where the reliability really shows up.
Why schema-first beats prompt-first
- The schema is versionable — it lives in your repository next to the code that consumes it.
- It is testable — you can assert contract coverage without calling a model.
- It fails fast — a schema the model cannot satisfy surfaces at development time, not at 3 a.m.
- It moves the ambiguity out of the prompt and into a machine-checkable artifact.
How Constrained Decoding Works
At inference time a language model does not pick "the next word." It produces a probability distribution over its entire vocabulary — tens of thousands of token candidates — and a sampling strategy picks one. Constraint techniques intervene between those two steps.
The step-by-step pipeline
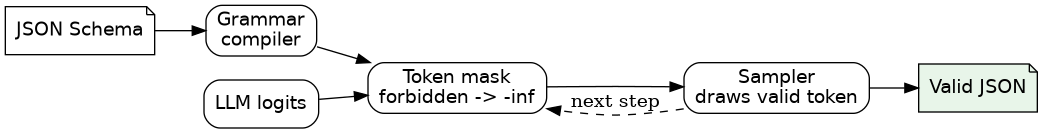
- Compile the schema. Your JSON Schema is translated into a representation the inference engine can evaluate incrementally — typically a context-free grammar, a state machine, or a compiled regular expression over token space.
- Advance the grammar state. After each generated token, the automaton advances to the set of positions the output is now in (for example: "inside the
currencystring, which must match^[A-Z]{3}$"). - Mask forbidden tokens. Every vocabulary token whose continuation would make the remaining output impossible to satisfy gets its logit set to negative infinity.
- Sample from what remains. The sampler draws only from tokens that keep every path to a valid completion open.
- Repeat until the grammar accepts. Generation ends when the automaton reaches an accepting state — usually a complete, schema-valid JSON object.
Tokenization is the hard part
The subtle difficulty is that JSON Schema operates on characters, while the model samples tokens. A single token can span a character boundary the grammar cares about — one token might contain ", "price": all at once. Engines handle this with techniques commonly described as token healing or token-level grammar projection: candidate tokens are checked by simulating their character expansion against the current grammar state, and tokens that overshoot a valid boundary are discarded.
This is also why constraints are not free. Masking requires per-step evaluation of the automaton against the vocabulary (or a smart prefix-indexed subset of it), which adds CPU work to every generated token.
What "valid by construction" really means
The guarantee is precise: the concatenation of generated tokens will be accepted by the grammar, and the grammar was compiled from your schema. It does not guarantee the content is true. A model can produce perfectly schema-valid nonsense — "invoice_total": -9000000 is a legal number. Constrained decoding fixes structure, not semantics. Downstream business validation is still required.
Grammars, Regular Expressions, and JSON Schema
Under the hood, engines reach for different formalisms:
| Formalism | Expressiveness | Compile cost | Best for |
|---|---|---|---|
| Regular expressions | Regular languages only | Very low | Flat types, simple enums |
| JSON Schema subsets | Declarative, structure-aware | Low to medium | Objects, arrays, required keys |
| Context-free grammars (GBNF, EBNF) | Nested structures, recursion | Higher | Arbitrary nesting, custom syntax |
Recursive structures — arrays of objects containing arrays of objects — are inherently context-free, which is why grammar-based approaches became the workhorse of open-source inference servers. llama.cpp popularized GBNF, a BNF-like grammar format where a JSON Schema can be mechanically compiled into a grammar file the sampler enforces. Other engines take a JSON Schema directly and compile it internally to an equivalent automaton.
A useful mental model: JSON Schema is the interface you write, the grammar is the implementation the sampler executes, and token masking is the runtime enforcement.
The Tooling Landscape
Python - schema as code
The dominant Python pattern pairs Pydantic models with a thin library that validates, retries, and passes the schema to the model. Instructor popularized this shape:
from pydantic import BaseModel, Field
from typing import Literal
import instructor
from openai import OpenAI

class Invoice(BaseModel):
    vendor: str = Field(description="Vendor name as printed on the document")
    currency: Literal["USD", "EUR", "GBP"]
    total: float = Field(gt=0)
    line_items: list[str]

client = instructor.from_openai(OpenAI())

invoice = client.chat.completions.create(
    model="gpt-4.1-mini",
    response_model=Invoice,
    messages=[
        {"role": "user", "content": document_text},
    ],
)
# `invoice` is already an Invoice instance - no json.loads, no try/except
Lower-level libraries such as Outlines and llguidance let you constrain a local model directly during generation, accepting JSON Schema, regex, or custom grammars. On the self-hosted side, vLLM exposes guided decoding backends and llama.cpp supports both JSON-schema mode and raw GBNF grammars, whether you call it through its server, bindings, or an SDK.
TypeScript - Zod at the boundary
On the Node side, Zod and TypeBox define schemas that double as runtime validators and can be converted to JSON Schema for the model:
import { z } from "zod";
import { zodResponseFormat } from "openai/helpers/zod";

const Extraction = z.object({
  sentiment: z.enum(["positive", "neutral", "negative"]),
  confidence: z.number().min(0).max(1),
  topics: z.array(z.string()).max(5),
});

const format = zodResponseFormat(Extraction, "extraction");
// pass `format` as response_format to a compatible API
The pattern is identical across languages: define the shape once, derive both the model constraint and the runtime validator from it. Duplicating the schema by hand in a prompt string and again in code is the most common source of contract drift.
Real-World Example - An Invoice Extraction Pipeline
Suppose you ingest PDFs of supplier invoices and need structured rows for an accounting system. The consuming code expects exact types because it writes directly to a database.
from pydantic import BaseModel, Field, field_validator
from typing import Literal
import re

class LineItem(BaseModel):
    description: str
    quantity: int = Field(gt=0)
    unit_price: float = Field(gt=0)

class Invoice(BaseModel):
    invoice_number: str
    issue_date: str = Field(pattern=r"^\d{4}-\d{2}-\d{2}$")
    currency: Literal["USD", "EUR", "GBP"]
    tax_rate: float = Field(ge=0, le=1)
    items: list[LineItem] = Field(min_length=1)
    total: float = Field(gt=0)

    @field_validator("total")
    @classmethod
    def total_must_match_items(cls, v: float, info) -> float:
        items = info.data.get("items")
        if items:
            subtotal = sum(i.quantity * i.unit_price for i in items)
            expected = round(subtotal * (1 + info.data["tax_rate"]), 2)
            if abs(v - expected) > 0.05:
                raise ValueError(f"total {v} does not match computed {expected}")
        return v
Notice the two-layer design:
- Structural constraints (
Literal,pattern,gt,min_length) are fed to the model so the generated tokens already satisfy them. - Semantic constraints (the total matching the line items) are business rules the model cannot see. They run after generation, and a mismatch triggers a targeted regeneration with an error message telling the model exactly what to fix.
A robust loop looks like this:
def extract(client, document_text: str, max_attempts: int = 3) -> Invoice:
    messages = [{"role": "user", "content": f"Extract the invoice:\n\n{document_text}"}]
    last_error = None
    for _ in range(max_attempts):
        if last_error:
            messages.append({"role": "user",
                             "content": f"Previous answer was wrong: {last_error}. Fix it."})
        invoice = client.chat.completions.create(
            model="gpt-4.1-mini",
            response_model=Invoice,
            messages=messages,
        )
        try:
            invoice.total_must_match_items(invoice.total,
                                           type("I", (), {"data": invoice.model_dump()})())
            return invoice
        except ValueError as e:
            last_error = str(e)
    raise RuntimeError(f"extraction failed after {max_attempts} attempts")
In real code you would invoke the validator through Pydantic's own API rather than the shim shown above — the point is the shape of the loop: constrain the structure, validate the meaning, retry only on semantic failure. Because structure can no longer fail, retries drop dramatically and become cheaper.
Performance, Cost, and Latency
Constrained decoding is not a zero-cost upgrade. Expect these effects:
- Added per-token overhead. Grammar evaluation and logit masking add work each step. On long outputs with complex grammars, throughput can drop noticeably; on typical short JSON payloads the effect is often modest. Measure with your own model and hardware.
- Fewer retries. The savings come from here. A pipeline that retried 15% of calls and now retries 1% usually comes out ahead even with slower decoding.
- Shorter outputs. Valid JSON has no preamble or apology, so token counts fall on the response side.
- Compile caching. Compiled grammars should be cached per schema version; recompiling on every request is a self-inflicted latency wound.
| Factor | Prompt-only JSON | Constrained decoding |
|---|---|---|
| Parse success rate | Model-dependent, often imperfect | Effectively 100% for supported schema subset |
| Semantic correctness | Model-dependent | Identical — constraints do not add truth |
| Per-token latency | Baseline | Slightly higher |
| Retry rate | High at scale | Low |
| Schema evolution | Edit the prompt, pray | Edit the schema, run contract tests |
Pitfalls and Cautions
Caution: Not every schema feature is supported by every engine. Recursive
$refdefinitions, someoneOf/anyOfcombinations, deeply nested conditionals, and exotic formats have historically had gaps in individual backends. Always validate your production schema against your exact model and inference stack — a schema that works in a vendor playground may be silently simplified or rejected elsewhere.
The most common mistakes teams make:
- Skipping validation entirely. Constraints guarantee shape, not semantics. Keep type checks and business rules in application code.
- Over-constraining free-text fields. Forcing
descriptioninto an enum destroys information. Constrain types and formats; let open fields stay open. - Forgetting streaming consumers. Partial JSON from a streaming response cannot be parsed until complete (or until a streaming JSON parser is used). Plan how your UI handles that.
- Schema drift across environments. The prompt, the constraint schema, and the consumer's validator must be generated from a single source of truth.
- Assuming universality. Older models, fine-tunes, and some local runtimes do not support guided decoding at all. Feature-detect rather than assume.
- Using one giant schema for everything. Small, purpose-built schemas are easier for models to satisfy semantically and easier for engines to compile.
A Practical Checklist
- Define the response schema in code with a typed model (Pydantic, Zod, TypeBox).
- Generate the JSON Schema from that model — never hand-write a second copy.
- Enable constrained decoding or structured outputs on the model you actually use.
- Keep business-rule validation in your application layer, after parsing.
- Add a bounded, observable retry loop that reports semantic failures as metrics.
- Cache compiled grammars keyed by schema version.
- Load-test with your real schema to measure the latency overhead honestly.
- Track schema version alongside model version — both change behavior.
Key Takeaways
- Structured outputs turn JSON reliability from a prompting gamble into a sampling constraint: forbidden tokens are masked before the sampler ever sees them.
- JSON Schema is the interface, a compiled grammar is the implementation, and token masking is the runtime enforcement.
- Constrained decoding guarantees structure, never truth — semantic validation and business rules still belong in application code.
- The highest-leverage pattern is a single typed model that generates both the model-side constraint and the runtime validator.
- Costs are real but usually favorable: modest per-token overhead in exchange for near-zero parse failures and far fewer retries.
- Audit your exact backend's supported schema subset before shipping; support varies across providers and inference engines.
Frequently Asked Questions
Does constrained decoding make hallucinations impossible? No. It guarantees the output matches your schema — an invented vendor name or a wrong total can still be perfectly well-formed. Constrained decoding fixes serialization, not accuracy.
What is the difference between JSON mode and structured outputs? JSON mode only guarantees syntactically valid JSON of any shape. Structured outputs additionally guarantee the JSON conforms to a specific schema — required keys, types, enums, and formats.
Is this a replacement for function calling? They complement each other. Function calling decides which tool gets invoked with what arguments; constraining decoding against the tool's parameter schema makes those arguments reliably parseable.
Do all models and inference servers support this? Most major hosted APIs do, and popular self-hosted engines such as vLLM and llama.cpp offer guided decoding or grammar modes. Older models, some fine-tunes, and lightweight runtimes may not — verify against your stack.
Which schema features tend to cause trouble?
Deeply recursive definitions, complex anyOf/oneOf unions, and rarely used keywords are the usual troublemakers. If a feature feels exotic, test it against your backend before relying on it.
How do I choose between a regex, a JSON Schema, and a custom grammar? Use JSON Schema for ordinary structured data — it is the most portable. Drop to a grammar when you need recursion or non-JSON syntax. Reserve regexes for flat, well-bounded fields where a full schema adds nothing.
Related Articles
- RAG Explained: A Practical Guide to Building AI-Powered Applications with Retrieval-Augmented Generation
- Model Context Protocol Explained: How to Connect AI Agents to Tools and Data with MCP
- Building Production-Ready AI Agents with LangGraph
- Property-Based Testing Explained: Finding Bugs Your Example-Based Tests Will Never Catch
- Mastering GraphQL: A Practical Guide to Flexible, Type-Safe APIs


Comments
Post a Comment