Exploratory Testing and Session-Based Test Management: A Practical Guide to Chartering, Note-Taking and Risk-Driven Discovery
Automation finds the bugs you already imagined. Exploratory testing finds the ones you didn't. Yet in most test strategies, exploratory testing is the least intentional activity in the building — a tester is told to "have a look around," clicks for twenty minutes, finds something odd, forgets it, and moves on. Nothing is recorded, nothing is learned, and the same ground gets re-covered next sprint by a different person.
This article explains how to treat exploratory testing as a disciplined engineering practice rather than unstructured tinkering. You will learn the difference between scripted, automated and exploratory testing; how Session-Based Test Management (SBTM) turns exploratory sessions into measurable, debriefable work; how to write effective charters; what note-taking techniques actually work under pressure; and how to integrate exploratory sessions into a modern CI/CD pipeline without slowing delivery.
Table of Contents
- What Exploratory Testing Actually Is
- Why It Survives the Automation Wave
- Session-Based Test Management: The Structure
- Writing Charters That Work
- Note-Taking: Timeline vs. Snapshot
- Debriefs and Metrics
- Real-World Example: A Checkout Flow Walkthrough
- Integrating Exploratory Testing into CI/CD
- Common Pitfalls
- Key Takeaways
- Frequently Asked Questions
- Related Articles
What Exploratory Testing Actually Is
Cem Kaner, one of the originators of the discipline, defines exploratory testing as simultaneous learning, test design and execution. That simultaneity is the point. In scripted testing you design tests first, then run them. In exploratory testing, every observation you make informs the next test you invent — the session is a feedback loop running at human speed.
The distinction matters because the three approaches fail differently:
| Approach | Strength | Blind spot |
|---|---|---|
| Scripted (manual) testing | Covers known requirements | Cannot anticipate unknowns; goes stale fast |
| Automated regression | Catches known bugs forever | Only finds what you wrote a test for |
| Exploratory testing | Finds unknowns, usability issues, requirement gaps | Hard to prove coverage; relies on skill |
Exploratory testing is not "no documentation." It is documentation of what you investigated rather than what you planned to execute beforehand. That is a subtle but crucial difference for reporting and audit purposes.
Why It Survives the Automation Wave
Every few years someone declares manual testing dead. It keeps not dying, for concrete reasons:
- Requirements arrive incomplete. A user story saying "user can check out" leaves a hundred questions about coupons, currency, timezones, timeouts and edge-case validation. Exploratory testing answers those questions by probing.
- Automation encodes assumptions. A Selenium or Playwright suite asserts what the team believed the system should do. When the belief is wrong, the test is wrong — or worse, the test is right and the bug is invisible because nobody thought to assert on it.
- Interfaces change in ways tooling notices late. A visually broken layout, a screen-reader announcement that makes no sense, a tooltip that covers the only button on a mobile viewport — these are common, high-impact defects that no assertion catches.
- Speed of feedback. A skilled explorer can evaluate a new build's risk areas within a 60-minute session, faster than writing new automation for an untested surface.
This does not make automation optional. The healthy model is a pyramid with a wide automated base and exploratory sessions focused on what automation cannot express — the new, the changed, and the risky.
Session-Based Test Management: The Structure
SBTM, formalized by James and Jon Bach, was invented to solve the credibility problem of exploratory testing. The unit of work is a session: a focused, uninterrupted block of time (typically 45–120 minutes) spent investigating a specific charter, followed by a short debrief.
A session has four properties:
- Charter — a mission statement describing the area and the type of testing (for example, "Explore the payment form with invalid data to find validation gaps").
- Timebox — a fixed duration. When time expires, the session ends even if testing feels unfinished; that unfinished feeling is itself information for the next charter.
- Focus — one tester, no email, no Slack interruptions. Multitasking destroys the associative thinking that makes exploratory testing work.
- Debrief — a short conversation with a test lead or stakeholder where the tester walks through the timeline of the session, findings and open questions.
The lifecycle of a test cycle looks like this:
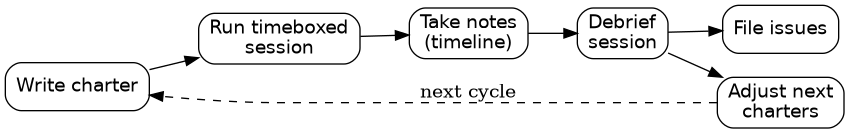
In practice a test cycle runs many overlapping sessions. A test lead (or the tester themselves in a small team) maintains a test board of session cards, each with a status: In Progress, Done, Blocked, or Needs Follow-up. This board becomes the primary artifact for status reporting — far more informative than "80% of test cases passed."
Writing Charters That Work
A weak charter produces a weak session. "Test the login page" gives the tester nothing to aim against. Effective charters use a simple formula:
Examples:
- Explore the password reset flow with expired and reused tokens to discover authentication edge cases.
- Explore the order history screen with a 3-year-old account to discover performance and pagination defects.
- Explore the mobile checkout in airplane mode to discover resilience and state-preservation gaps.
- Explore the admin dashboard with a screen reader to discover accessibility regressions.
Good charters are:
- Narrow. One surface, one risk type. If a session keeps wandering into a new area, that new area deserves its own charter next cycle.
- Risk-oriented. They target what hurts most when it breaks: money, data integrity, security, new code.
- Timebox-compatible. A charter that could not conceivably be explored in 90 minutes is too broad.
It also helps to declare a test tour — a themed collection of related charters. A "money tour" covers checkout, refunds, coupons and tax; a "data tour" covers import, export, bulk edit and deletion. Tours give the test board coherence and make it easy to see which risk families are under-explored.
Note-Taking: Timeline vs. Snapshot
The biggest quality lever in exploratory testing is disciplined note-taking. Your memory during a session is a shared resource: the part of your brain remembering what you clicked is not available for thinking about why that response looked odd.
Two techniques cover almost every situation:
- Timeline notation. One chronological line per meaningful observation:
10:14 Entered expired coupon → error shown but cart total unchanged. Timelines reconstruct the session during debrief and naturally produce a trace of coverage. - Screencast with annotation. Tools like OBS, macOS QuickTime or the session recording built into some exploratory-testing apps capture the screen and audio. Recording pairs extremely well with timelines — the timeline indexes the video.
A third technique, snapshot boxes (small ruled areas capturing a test idea, the result, and a pass/fail mark), is useful when you want near-test-case rigor for a bounded surface, but it is slower and rarely necessary.
Regardless of technique, capture three things consistently:
- What you intended to check (the test idea).
- What you actually observed (facts, not interpretations — "the total stayed at €49.99" rather than "the total was wrong").
- The evidence — a screenshot, a HAR file, a server log line, a video timestamp.
Facts are debatable; interpretations are not. Keeping observation and conclusion separate makes bug reports dramatically more actionable.
Debriefs and Metrics
The debrief converts a private session into shared knowledge. A good debrief takes 10–15 minutes and answers four questions:
- What did you learn that we did not know before the session?
- What bugs did you find, and where were they filed?
- What risks did you cover, and which remain uncovered?
- What charter should come next?
This structure surfaces the most valuable output of exploratory testing — updated risk models — not just defect counts.
The classic SBTTM-inspired metric is percentage of session time spent on testing versus setup and paperwork. Aim above 80%. Other useful signals include:
- Number of sessions per cycle and their coverage map (which tours or risk areas were touched).
- Defects found per session, split by severity — a cycle full of cosmetic bugs and no functional ones often means charters are aimed at the wrong risk.
- Percentage of sessions requiring a follow-up charter — high values suggest charters are too broad.
Caution: Do not turn session metrics into targets. The moment "defects per session" becomes a quota, testers will manufacture bugs and stop reporting near-misses. SBTM metrics are for steering the test strategy, never for evaluating individuals.
Real-World Example: A Checkout Flow Walkthrough
Consider an e-commerce team two weeks before a release. The automated Playwright suite covers happy-path checkout in three browsers; contract tests validate the payment-service interface; the API suite checks response codes. Everything is green. The product owner asks for one exploratory cycle on the checkout flow.
A test lead writes five charters from the money tour:
- Explore checkout with mixed discount rules to discover calculation and rounding errors.
- Explore payment failure paths (declined card, 3DS timeout, double-click submit) to discover duplicate-charge risks.
- Explore checkout on a throttled 3G connection to discover loading and retry behavior.
- Explore address entry with international formats to discover validation gaps.
- Explore post-payment redirects (success, cancel, browser back) to discover order-state inconsistencies.
Each session runs 90 minutes with timeline notes. Session 2 finds that double-clicking "Pay now" submits two payment intents — the first succeeds, the second is declined, and the user sees an error even though their money was taken. No automated test caught this because the happy-path test only ever clicked once. Session 4 finds that Japanese address fields silently truncate at 40 characters, corrupting shipment data for a market the team recently entered.
The debrief produces two immediate follow-up charters on payment idempotency and address validation, plus a backlog of automation tasks: the double-click scenario becomes a Playwright test with request interception, the truncation case becomes an API-level property test on the address validator.
That is the symbiosis in practice — exploration finds the gap, automation locks the fix in place forever.
Integrating Exploratory Testing into CI/CD
Exploratory testing is not an argument against pipelines; it is a component of them. Practical patterns for fitting sessions into continuous delivery:
- Risk-triggered sessions. Every pull request that touches a high-risk area (payments, auth, data migration) automatically enqueues a 30-minute exploratory session on the preview environment before merge.
- Release-candidate sessions. A fixed timebox (for example, two 90-minute sessions per release candidate) is reserved on the test board and is not skippable for schedule reasons.
- Post-deploy smoke exploration. Right after a production deploy, a tester performs a short charter-based pass on the changed surfaces while metrics are being watched — this catches deployment-configuration issues that staging never exhibits.
- Session notes linked to commits. Storing session notes in the repo (a simple Markdown file per session, or a ticket attachment) makes exploration auditable and searchable.
For a deeper treatment of the pipeline side of quality gates, see our related coverage of shift-left testing and test impact analysis.
Common Pitfalls
Teams adopting SBTM typically hit four failure modes:
- Charters that are really test cases. "Verify that the login button returns a 200 response" is a script. Charters must leave room for the tester to invent what to try next.
- Skipping the debrief. Without debriefs, insights evaporate. If sessions are never debriefed, the practice degrades into exactly the untracked poking it was meant to replace.
- Running sessions during interruptions. A 90-minute session with three Slack interruptions produces shallow coverage. Protect the timebox; it is shorter than most meetings it will replace.
- Measuring the wrong thing. Counting raw bugs rewards noise. Track risk coverage and the quality of insights instead.
A note on tooling: exploratory testing is deliberately low-tooling. A timer, a note file, a screencaster and a bug tracker cover nearly all needs. Heavyweight "exploratory testing platforms" exist, but the discipline's value comes from thinking, not from a dashboard.
Key Takeaways
- Exploratory testing is simultaneous learning, test design, and execution — it finds the bugs that scripted and automated approaches cannot imagine.
- Session-Based Test Management gives exploratory testing credibility through charters, timeboxes, structured notes, and debriefs.
- Good charters follow a simple formula: explore a target, with a technique or constraint, to discover a type of information.
- Timeline note-taking plus screencasting preserves session evidence and makes debriefs precise and actionable.
- Debriefs and the test board — not defect counts — are the real artifacts of a healthy exploratory practice.
- Pair exploration with automation: let humans find the unknown, then encode every confirmed fix as a permanent automated test.
Frequently Asked Questions
Is exploratory testing just ad-hoc testing with better branding? No. Ad-hoc testing has no charter, no timebox, no notes and no debrief. SBTM adds exactly those four controls, which is what turns an informal activity into a reportable, improvable practice.
How long should a session be? Most teams settle on 60–90 minutes. Shorter sessions struggle to build enough context; longer sessions lose focus and make debriefs unwieldy. Start at 90 minutes and adjust based on your debrief feedback.
Who should run exploratory sessions — developers or testers? Both, at different times. Developers exploring their own new feature before opening a PR catch shallow issues cheaply. Testers exploring with fresh eyes and domain context catch deeper requirement and interaction gaps. Pairing the two in a shared session is also highly effective.
Does exploratory testing replace automated regression suites? No, and it should not. Automation provides the fast, repeatable baseline for known behavior. Exploratory testing spends human attention on the unknown. Mature teams run both and use exploration to feed new cases into automation.
How do I report exploratory test results to management? Report against the test board: charters completed, risk areas covered, defects filed by severity, and open risks with recommended follow-up. This communicates coverage in business terms, unlike a raw pass/fail count.
Related Articles
- Shift-Left Testing: Integrating Quality Earlier in the Software Development Lifecycle
- Testcontainers Explained: Reliable Integration Testing with Real Dependencies
- Flaky Tests Explained: A Practical Guide to Finding and Eliminating Test Unreliability
- Property-Based Testing Explained: Finding Bugs Your Example-Based Tests Will Never Catch
- Accessibility Testing in 2026: A Complete Guide to Building Inclusive Software


세션을 결함 개수로 평가하지 말자는 경고가 특히 중요해 보입니다. 결제 버튼을 두 번 눌렀을 때의 예시처럼, 관찰한 현상과 원인 추정을 분리해서 적으면 개발자가 재현하기도 쉽겠네요. 회고에서 아직 확인하지 못한 위험과 다음 세션의 질문을 한 쌍으로 남기면, 시간 제한 때문에 멈춘 탐색도 이어가기 좋겠습니다.
ReplyDelete