DORA Metrics Explained: Measuring and Improving Your Software Delivery Performance
Every engineering organization wants to know the same thing: are we getting better at shipping software, or are we just getting busier? Story points, lines of code, and seat utilization answer the wrong questions. DORA metrics answer the right ones — how fast can you deliver changes, and how often do those changes break something for your users?
DORA metrics are four (now five) measures of software delivery performance, originally popularized by the DORA research team (DevOps Research and Assessment) through years of industry surveys and the book Accelerate. They are designed to be leading indicators of organizational performance: teams that score well on them tend to deliver more value with less burnout.
In this guide we'll break down each metric, show how elite teams compare with low performers, explain how to collect the data from the tools you already use, and — most importantly — show how to improve the numbers without gaming them.
Table of Contents
- What Are DORA Metrics?
- The Four Core Metrics in Detail
- Elite vs. Low Performers
- How Delivery Performance Maps to the Pipeline
- How to Collect DORA Metrics
- How to Improve Each Metric
- A Real-World Improvement Scenario
- Common Pitfalls: How Teams Game the Numbers
- Key Takeaways
- Frequently Asked Questions
- Related Articles
What Are DORA Metrics?
The DORA research program studied software delivery practices across thousands of teams and identified a small set of metrics that reliably separate high-performing from low-performing organizations. Rather than measuring effort, these metrics measure outcomes: the speed and stability of the path from a code commit to running in production.
The four core metrics are:
- Deployment Frequency — how often you successfully deploy to production.
- Lead Time for Changes — how long it takes a commit to reach production.
- Change Failure Rate — what percentage of deployments cause a failure in production.
- Time to Restore Service — how quickly you recover when a change causes an outage.
Later research added reliability as a fifth dimension, reflecting the fact that speed means nothing if the service is chronically down for users. Reliability is often expressed through the service level objectives and error budgets your SRE practice already tracks.
Important note: DORA metrics are a diagnostic tool, not a scoreboard for individual engineers. They are meant to evaluate the system of work — pipelines, environments, review processes, architecture — not people. Using them to rank individuals almost always destroys the signal and the trust.
The Four Core Metrics in Detail
Deployment Frequency
Deployment Frequency measures how many times per day, week, or month your team successfully releases software to production. "Successfully" matters: a deploy that is rolled back five minutes later still counts as a deployment, but a pipeline that fails before reaching production does not.
Small, frequent deployments are correlated with lower risk per change. When each deploy contains a tiny diff, a bug introduced is easy to spot, easy to isolate, and easy to revert. The opposite extreme — a release train every two weeks containing hundreds of changes — makes every incident a forensic puzzle.
Typical targets look like:
- Elite: on-demand, multiple deploys per day (hourly or more often)
- High: between once per day and once per week
- Medium: between once per week and once per month
- Low: once per month or less
Lead Time for Changes
Lead Time for Changes measures the elapsed time from the moment a developer commits code to the moment that code is running in production. It captures everything that happens in between: code review, CI, QA, approval gates, release scheduling, and the deploy itself.
Lead time is a proxy for how quickly your organization can respond to a business request or a security patch. A two-hour lead time means a critical fix can be in users' hands the same morning. A three-week lead time means you are structurally incapable of urgency, no matter how hard individuals work.
Note that lead time and deployment frequency are different signals. A team can deploy on demand but still have long lead times if work sits in review queues — or the reverse.
Change Failure Rate
Change Failure Rate is the percentage of deployments that result in a degraded service requiring remediation: a hotfix, a rollback, a patch deploy, or an incident. If you deploy ten times and two of those deploys cause a production problem, your change failure rate is 20%.
This metric is the stability counterweight to the two speed metrics. It prevents the classic dysfunction of "shipping fast" by breaking things constantly. Elite teams keep change failure rates in the single digits; a rate above 30% is a signal that testing, environments, or architecture need attention.
Time to Restore Service
Time to Restore Service measures how long it takes to recover normal service after an incident caused by a change (some definitions broaden it to any production failure). It is arguably the metric users care about most: they do not care how fast you deploy, they care how fast you fix.
Time to restore is influenced far more by detection and response than by raw engineering speed. Good observability, clear runbooks, automated rollbacks, and on-call readiness compress restore time dramatically — often more than writing better code does.
Reliability: The Fifth Measure
More recent DORA research elevated reliability to a first-class metric because delivery speed paired with chronic instability is not performance — it is risk-taking. In practice, most organizations measure reliability with the SRE toolkit: availability targets, error budgets, latency percentiles, and burn-rate alerts on your SLIs.
Caution: optimizing any single DORA metric in isolation leads to pathological behavior. Maximizing deployment frequency while ignoring change failure rate produces a team that breaks production five times a day. Always read the four metrics as a balanced system.
Elite vs. Low Performers
The following table summarizes the general performance bands reported by DORA research. Treat these as directional guidance rather than pass/fail thresholds — your context (regulatory burden, monolith vs. microservices, team maturity) shifts what is realistic.
| Metric | Elite | High | Medium | Low |
|---|---|---|---|---|
| Deployment Frequency | On demand (multiple per day) | Between daily and weekly | Between weekly and monthly | Monthly or less |
| Lead Time for Changes | Less than one day | Between one day and one week | Between one week and one month | More than one month |
| Change Failure Rate | 0–15% | 16–30% | 16–30% | Above 30% |
| Time to Restore Service | Less than one hour | Less than one day | Between one day and one week | More than one week |
Two observations are worth internalizing:
- Speed and stability correlate positively. The common intuition that faster teams make more mistakes is not supported by the data; elite teams are fast and stable, because their delivery system is better engineered.
- You cannot buy your way out of a slow system. More servers do not shorten a three-day manual approval queue. Most bottlenecks are process and architecture, not hardware.
How Delivery Performance Maps to the Pipeline
Each metric attaches to a different segment of your delivery pipeline. Seeing them laid out end-to-end makes it obvious where a slow or fragile stage hurts which number:
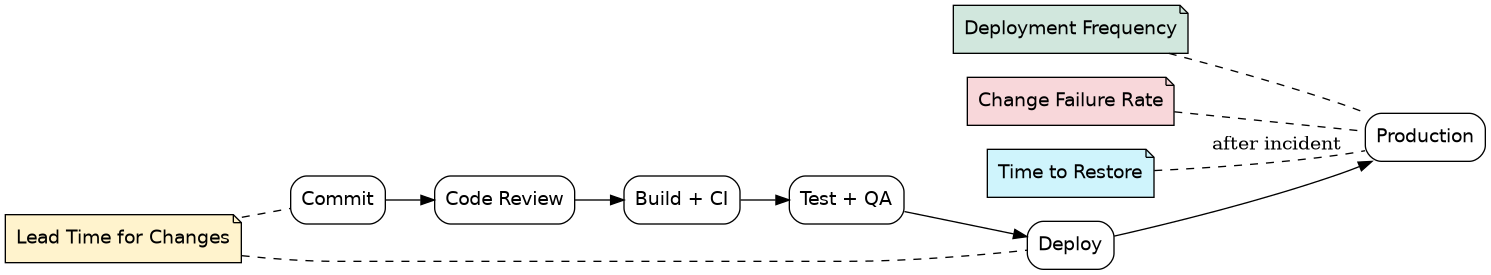
- Lead Time spans commit → production.
- Deployment Frequency is counted at the production edge.
- Change Failure Rate is observed in production shortly after each deploy.
- Time to Restore starts when an incident is detected in production.
How to Collect DORA Metrics
The good news: most teams already have the raw data. Collection is mostly a matter of joining events from a few systems.
| Metric | Primary data source | Event to record |
|---|---|---|
| Deployment Frequency | CI/CD system (GitHub Actions, Jenkins, Argo CD) | Successful production deploy |
| Lead Time for Changes | Version control + CI/CD | First commit on a change → prod deploy timestamp |
| Change Failure Rate | Incident tracker + deploy log | Failed deploy / deploy linked to an incident |
| Time to Restore | Monitoring + incident tooling (PagerDuty, Opsgenie) | Incident start → service restored |
Practical tips for collection:
- Define "production" explicitly. Staging, preview environments, and canary slots are not production. Ambiguity here invalidates every downstream number.
- Define "a change." Squash-merged pull requests should count once, not once per commit. Decide whether a merge to main or a prod deploy is your unit of work, and document it.
- Define "failure." Does a rolled-back canary that never served real traffic count? Does a deploy that triggers an alert but no user impact count? Write the rule down before you measure.
- Automate the joins. A small pipeline that pulls deploy events from your CI system, correlates them with commits, and writes to a metrics store beats a monthly spreadsheet exercise.
- Start with a baseline, not a target. Measure four to eight weeks before setting any goals, or you will be optimizing a number you invented.
Tools in this space include the four-keys style dashboards built on top of your CI/CD and incident APIs, OpenTelemetry-based pipelines for traces and deploys, and straightforward SQL over your existing event tables. The tooling is rarely the hard part — the definitions are.
How to Improve Each Metric
Improving Deployment Frequency
- Automate the path to production. Every manual step between green CI and production is a throttle. Move to automated, auditable pipelines with progressive delivery.
- Shrink the batch size. Smaller pull requests deploy more often and fail more cheaply. Trunk-based development with short-lived branches supports this naturally.
- Untangle releases from deployments. Feature flags let you deploy continuously while releasing gradually — decoupling "code is live" from "users can see it."
Improving Lead Time for Changes
- Attack queue time, not coding time. In most organizations, code spends far more time waiting for review, environments, and approvals than being written. Measure the waiting, not the typing.
- Make environments self-service. Ephemeral preview environments remove the shared-staging bottleneck that silently adds days.
- Parallelize pipelines. Split unit tests, integration tests, and security scans so they run concurrently; cache dependencies between runs.
Improving Change Failure Rate
- Shift verification left. Contract tests, integration tests, and policy-as-code admission checks catch problems before production rather than after.
- Harden environments. Configuration drift between staging and production is a classic source of "it worked in staging" failures. Immutable infrastructure and image promotion reduce the gap.
- Use progressive delivery. Canary and blue-green deployments let a bad change touch 1% of traffic instead of 100%, and automatic rollback converts a would-be incident into a non-event.
Improving Time to Restore Service
- Detect faster than you fix. Alerting on symptoms users experience (latency, error rate) rather than causes (CPU) cuts minutes out of every incident.
- Automate rollback. If the pipeline that deploys in two minutes can also revert in two minutes, restore time collapses.
- Practice. Blameless postmortems, game days, and runbooks that are actually rehearsed turn restore time from heroic improvisation into routine procedure.
A Real-World Improvement Scenario
Consider an illustrative scenario (a composite, not a specific published case): a mid-sized SaaS team deploys twice a month through a release train, has a lead time of about eighteen days, a change failure rate near 35%, and restores service in roughly two days.
The team's diagnosis:
- Deployment frequency was low because releases were batched and coordinated with manual QA and a change-approval board.
- Lead time was long because work waited: three days for code review, five days for a shared staging slot, four days for scheduled release windows.
- Change failure rate was high because staging diverged from production and each release bundled dozens of unrelated changes.
- Restore time was long because rollbacks were manual database-and-config affairs with no rehearsal.
Their sequence of changes:
- First, automated rollback and deploy-time health checks — this improved restore time with minimal risk.
- Second, environment parity via immutable images promoted from staging to production — this cut change failure rate.
- Third, splitting the release train into per-merge deployments behind feature flags — this raised deployment frequency while keeping user-facing release cadence unchanged.
- Fourth, parallel test stages and cached builds — this shortened lead time.
Within one quarter the team was deploying daily, restoring within an hour, and seeing failure rates in the mid-single digits — not because people worked harder, but because the delivery system was redesigned around the constraints the metrics exposed.
Common Pitfalls: How Teams Game the Numbers
Metrics change behavior. Some behaviors are desirable; others are perverse. Watch for:
- Splitting deploys into tiny meaningless pushes to inflate deployment frequency. Frequency is only valuable when paired with change failure rate and user value.
- Excluding "hard" changes from the denominator of change failure rate (e.g., declaring database migrations out of scope).
- Silencing alerts to reduce incident counts, which destroys the time-to-restore signal and hurts users.
- Rewriting lead time's start point — measuring from "when the ticket was estimated" instead of "when the first commit landed."
- Ranking individuals with team-level metrics, which discourages collaboration and encourages local optimization.
Rule of thumb: if a metric can be improved without improving the experience of your users or the sustainability of your team, your definition of the metric is wrong. Fix the definition before you set targets.
A healthy rollout looks like this: baseline for a month, agree on definitions with the whole team, publish a dashboard, discuss trends in retrospectives, and pick one constraint at a time to attack. Metrics are a conversation starter, not a verdict.
Key Takeaways
- DORA metrics measure delivery outcomes — deployment frequency, lead time for changes, change failure rate, and time to restore service — plus reliability as a fifth dimension.
- High delivery performance is both faster and more stable; speed and quality are not a trade-off at the system level.
- Every metric maps to a specific segment of your commit-to-production pipeline, which tells you exactly where to look for bottlenecks.
- Data collection is usually a join across your CI/CD system, version control, and incident tooling — definitions matter far more than tooling.
- Improve metrics by removing queue time, shrinking batch size, guaranteeing environment parity, and automating rollback, not by pressuring individuals.
- Never optimize one metric in isolation; always read speed and stability together to avoid gaming.
Frequently Asked Questions
Q1. Are DORA metrics a good way to evaluate individual developers? No. They describe the performance of the whole delivery system — pipeline design, review process, architecture, and operational readiness. Applying them to individuals invites gaming and erodes collaboration. Use them to improve the system, not to judge people.
Q2. What if our deployment frequency is low because we're heavily regulated? Regulation constrains how you deploy, not necessarily how often. Automated evidence collection, immutable artifacts, and approval workflows built into the pipeline can preserve auditability while enabling frequent small releases. Many regulated teams find that frequent, small, well-evidenced changes are actually easier to audit than rare large ones — though your specific compliance regime will determine what's possible.
Q3. How long before we see improvement after changing our process? It varies. Quick wins like automated rollback and pipeline parallelism often move restore time and lead time within weeks. Structural changes — environment parity, splitting the release train, adopting feature flags — typically take a quarter or more to show up clearly in trend data. Measure a baseline first so you can tell real change from noise.
Q4. Which metric should we improve first? There's no universal order, but a common heuristic is: start with time to restore service (it's usually the safest first win and builds confidence), then change failure rate (stability unlocks speed), then deployment frequency and lead time. If one metric is catastrophically off-track relative to the others, start there.
Q5. Do DORA metrics replace SLIs, SLOs, and error budgets? No — they're complementary. DORA metrics describe how you deliver changes; SLOs and error budgets describe how reliably the service behaves for users. A mature engineering organization tracks both: delivery metrics to improve the pipeline, reliability metrics to govern risk.
Related Articles
- Service Level Objectives and Error Budgets: The SRE Guide to Measuring Reliability
- Feature Flags in DevOps: The Complete Guide to Progressive Delivery and Safe Releases
- OpenTelemetry in DevOps: Unified Traces, Metrics, and Logs for Modern Observability
- Push vs Pull Deployment Models - Understanding GitOps and Continuous Delivery
- Platform Engineering in 2026: Building Your Internal Developer Platform from Scratch


Comments
Post a Comment