Test Data Management Explained: Fixtures, Factories, Seeding and Synthetic Data
Ask five experienced testers what slows their automation down and you get four different answers: the CI queue, flaky selectors, waiting for staging to be reset — and, eventually, test data.
Test data is the invisible half of test automation. Nobody demos a selector strategy; everybody feels the cost of a fixture that leaks a row into the next test, or a staging database wiped mid-run by a teammate. Your tests are only as trustworthy as the data underneath them.
This guide covers the four properties a healthy dataset must have, the patterns that keep it maintainable, reproducible seeding, when synthetic generation beats hand-written literals, and how to work with production-derived data without breaking the law.
Table of Contents
- Why Test Data Is the Hardest Part of Testing
- The Four Properties of a Healthy Test Dataset
- Patterns: Literals, Builders, Factories and Fixtures
- Seeding a Database Reproducibly
- Synthetic Data: Fakers and Boundary Values
- Using Production Data Safely
- Real-World Example: An End-to-End Checkout Suite
- Test Data in the CI/CD Pipeline
- Common Pitfalls and How to Avoid Them
- Key Takeaways
- Frequently Asked Questions
Why Test Data Is the Hardest Part of Testing
Test code is deterministic: you write it, read it, refactor it. Test data is a shared, mutable resource living outside your editor. That single difference produces most classic automation failures.

Take a single checkout test. It needs a user with a known email, a product with stock and a tax category, a shipping zone covering that address, an expired payment method for the failure path, and a clean order table. Five dependencies, none of which live in the test file. Multiply by 200 tests running 8-wide in CI, plus a QA engineer in the same environment, and the problems compound fast.
| Symptom | Root cause | Typical cost |
|---|---|---|
| Passes locally, fails in CI | Residual env data, stale local DB | Debugging hours, then a "retry" that hides it |
| Fails only when run with others | Shared mutable state, no isolation | Flaky pipeline, lost trust in the suite |
| Failure message unreadable | Random IDs and timestamps in the diff | 20+ minutes to see what changed |
The cost is not in creating data, it is in reasoning about it later. A test that fails at 3 a.m. and prints a diff full of UUIDs is unusable, however good the assertion.
Note: A test that cannot explain which data it used is a test you cannot debug. Unseeded randomness, implicit ordering and hand-edited JSON are the three most common reasons a failure takes hours to read.
The Four Properties of a Healthy Test Dataset
Nearly every practice in this field falls out of four properties: deterministic, identifiable, isolated and referentially complete.
1. Determinism
If a test fails in CI you must be able to regenerate the exact dataset locally. Unseeded randomness is the number one enemy of reproducibility.
2. Identifiability
user_8f3a91@example.test tells you far more than 2b7c…@mail.test. Derive the interesting attribute from a stable, human-readable token and encode the test's intent in it.
3. Isolation
No shared rows, no "run this one first" dependencies, no reliance on leftovers. A test must run in any order, in parallel, and twice in a row.
4. Referential integrity
Real systems are graphs. A user has an address; the address has a country; the country determines tax and shipping eligibility. Data that satisfies flat rows but breaks these relationships produces failures that look like application bugs and are not — "the checkout total is wrong" becomes "the tax rate came from the wrong country", which you can actually fix. Model that graph in your factories.
Patterns: Literals, Builders, Factories and Fixtures
Use the simplest pattern that still satisfies the four properties.
Literals: when hard-coding wins
Hand-written constants are correct when the value is the assertion. A test expecting a 409 FREE_TIER_EXCEEDED on the sixth free seat should use a named MAX_FREE_TIER_USERS constant, not faker.number.int({ min: 5, max: 5 }). Generate the boundary and the test drifts the moment the rule changes — and the reader loses the only documentation the value had.
The Builder pattern: explicit about only what matters
A builder lets the caller state deltas from a valid default. Use it when several fields interact and the reader needs to see them side by side.
import dataclasses
from datetime import date, timedelta

@dataclasses.dataclass
class User:
    email: str
    country_code: str = "US"
    trial_ends_at: date | None = None

def a_user(**overrides) -> User:
    """A valid user, with only the fields you care about spelled out."""
    return dataclasses.replace(User(email="default.user@example.test"), **overrides)

assert a_user(trial_ends_at=date.today() + timedelta(days=3)).trial_ends_at > date.today()
assert a_user(trial_ends_at=date.today() - timedelta(days=1)).trial_ends_at < date.today()
assert a_user(country_code="DE").email == "default.user@example.test"  # defaults survive
A builder gives you a valid baseline for free, so each test pays only for the one or two fields it exercises — and it kills the copy-paste avalanche where 200 tests hand-roll slightly different user objects.
The Factory pattern: volume with intent
Builders are for one object. Factories are for many objects, and for objects that must be persisted or sent across a network boundary. A factory owns the defaults, the naming convention and the cleanup story.

import { faker } from '@faker-js/faker';

// Seeded instance: same seed, same data, every time.
const f = faker.createInstance({ locale: 'en' });
f.seed(20260930);

export const userFactory = (overrides = {}) => ({
  email: `user.${f.string.alphanumeric(8)}@example.test`,
  country_code: 'US', is_verified: true, plan: 'free',
  ...overrides,
});

export const orderFactory = (overrides = {}) => ({
  currency: 'USD', status: 'created', shipping_country: 'US',
  lines: [{ sku: `SKU-${f.string.alphanumeric(8)}`, quantity: 1, unit_cents: 2500 }],
  ...overrides,
});
Two details do the heavy lifting. The faker instance is seeded, so any CI failure reproduces exactly. And identifiers are prefixed (SKU-, user.), so a 40-line diff of a failing order is readable without opening the database. Python teams get the same idea from factory_boy.
Fixtures: scope and lifecycle
A fixture is the lifecycle wrapper around your data: when is it created, how wide is it, and when is it destroyed?
| Scope | Created | Destroyed | Use it for |
|---|---|---|---|
Session / global |
Once per run | End of run | Reference data: countries, currencies, flags |
| Module | Once per file | End of file | Expensive shared setup (a seeded warehouse tree) |
| Function | Per test | After each test | The default for anything that mutates |
// e2e/fixtures.js — Playwright style
import { test as base, expect } from '@playwright/test';

export const test = base.extend({
  // Per test: a clean, disposable, identifiable customer.
  customer: async ({ page, request }, use, testInfo) => {
    const res = await request.post('/api/test/users', {
      data: { label: testInfo.title.slice(0, 40) },   // greppable in CI logs
    });
    const user = await res.json();
    await page.goto(`/login?token=${user.one_time_token}`);
    await use(user);
    await request.delete(`/api/test/users/${user.id}`);   // explicit teardown
  },

  // Once per worker: slow, read-mostly catalogue data.
  catalog: [async ({ request }, use) => {
    await use(await (await request.post('/api/test/seed')).json());
  }, { scope: 'worker' }],
});

export { expect };
Deriving the label from testInfo.title is a small trick with a large payoff: search your CI logs for the test name and every row it created is already tagged.
Caution: Prefer explicit teardown over "wipe the database after each test." Truncating tables is slow, breaks parallel workers sharing a database, and destroys the evidence you need when something fails at 3 a.m. Delete by scope, or use a throwaway database you can drop and recreate.
Seeding a Database Reproducibly
Unit-level data can live in memory. Anything crossing a service boundary needs a real datastore. The rule is the same for every engine: migrations first, seed second, known version.
-- migrations/004_seed_reference_data.sql
INSERT INTO countries (code, name, tax_rate_bp, requires_vat_id)
VALUES ('US', 'United States', 0,    FALSE),
       ('DE', 'Germany',      1900, TRUE)
ON CONFLICT (code) DO NOTHING;
Reference data belongs in migrations because it is an invariant of the schema. Scenario data belongs in seeders the tests invoke, not in a bootstrap that runs once per container — that split makes scenario resets take milliseconds.
# tests/seed.py — idempotent: safe to call before every test
SCENARIOS = {
    "insufficient_stock": [{"email": "buyer.lowstock@example.test", "cc": "US"}],
    "vat_id_required":     [{"email": "buyer.germany@example.test", "cc": "DE"}],
}

def seed(engine, name: str) -> None:
    """Delete the scenario's rows, then reinsert them. Safe under repetition."""
    with engine.begin() as conn:
        conn.execute(text("DELETE FROM scenario_rows WHERE scenario = :n"), {"n": name})
        for u in SCENARIOS[name]:
            conn.execute(text("INSERT INTO users (email, country_code) VALUES (:e, :c)"),
                         {"e": u["email"], "c": u["cc"]})
# One scenario name in, deterministic rows out.
python -m tests.seed insufficient_stock && pytest tests/test_checkout.py -k insufficient_stock
Give every scenario a declared teardown counterpart and assert in CI that no rows from previous runs survive — leftovers are the mechanism behind most order-dependent flakiness.
Synthetic Data: Fakers and Boundary Values
Synthetic data is data you invent rather than copy. Most of it is trivial; the interesting part is the boundary conditions, because that is where bugs live.

| Library | Language | Best for |
|---|---|---|
Faker |
Python | People, companies, addresses, payment placeholders |
@faker-js/faker |
JS / TS | Locale-aware data in Node and browser tests |
AutoFixture, Bogus |
C# | Fixture-based and fluent seeded generation |
Hypothesis |
Python | Property-based generation of edge-case inputs |
Generated data can be more realistic than hand-written fixtures — until a library quietly emits a 40-character street name your validator rejects. It is also less legible, which is why you pin the seed and prefix the identifiers.
Boundary values beat averages:
| Field | Weak input | Strong inputs |
|---|---|---|
email |
a@b.co |
empty, 254-char local part, no @, IDN domain |
quantity |
3 |
0, -1, max int, 1.5, "3" as a string |
currency |
USD |
usd, XXX (invalid ISO 4217), US D |
This is where property-based testing pays off: hand the framework a generator for the type and a property that must always hold, and let it search for you.
from hypothesis import given, strategies as st

@given(st.text(min_size=0, max_size=320))
def test_email_formatter_never_crashes(raw):
    assert len(format_email(raw)) <= 320   # a property, not an expected value
Using Production Data Safely
Copying a production snapshot into a test environment is the fastest route to realistic data and the fastest route to a compliance incident. Real datasets contain names, addresses, payment tokens and health data that no test ticket needs.
If you must use production-derived data, treat it as a pipeline with mandatory gates.
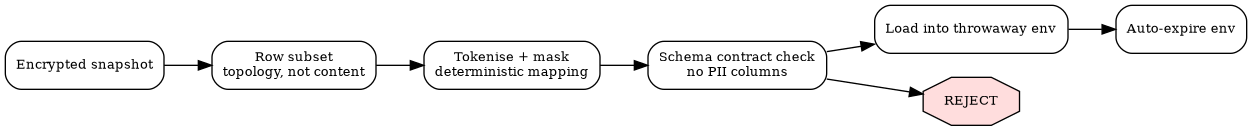
- Subset, don't copy. Take rows that reproduce the shape of production — a thread with 40 replies, an account with 12 payment methods — not whole tables.
- Tokenise deterministically. Replace originals with a stable fake via a keyed hash, so joins still line up. Randomised replacement breaks referential integrity and turns a realistic dataset into noise.
- Keep structural metadata. What causes bugs is statistics: length, cardinality, nullability, date spread, referential depth. Preserve those exactly — they are not personal data.
- Never copy free-text as-is. Notes, tickets and comments are pure PII. Replace them with same-length filler, and expire the environment with a scheduled job.
Important: Whether a snapshot may lawfully be copied into a test environment depends on your jurisdiction, your contracts and your stated purpose. Under the GDPR, pseudonymised data can still count as personal data when re-identification is reasonably possible, and the legal basis for processing must be documented. Treat that as a question for your privacy or legal team, not a technical decision — and default to fully synthetic data whenever it can express your scenario.
Real-World Example: An End-to-End Checkout Suite
One scenario file, one seed, no shared state: an e-commerce checkout handling multi-country tax and a deliberate stock failure.
// e2e/checkout.spec.js
import { test, expect } from './fixtures.js';
import { orderFactory, userFactory } from '../factories/index.js';

test.describe('checkout', () => {
  test('applies German VAT and captures an order', async ({ page, customer, catalog, request }) => {
    const user = userFactory({ country_code: 'DE', email: customer.email, vat_id: 'DE999999999' });
    const product = catalog.find(p => p.country_code === 'DE' && p.stock > 5);
    const order = orderFactory({
      lines: [{ sku: product.sku, quantity: 2, unit_cents: 1999 }],
      shipping_country: 'DE',
    });

    const created = await request.post('/api/orders', { data: { user, order } });
    expect(created.status()).toBe(201);
    await page.goto(`/checkout/${created.json().id}`);
    await page.getByRole('button', { name: 'Place order' }).click();

    // 3998 cents + 19% German VAT (1948 cents, rounded) = 5946 cents
    await expect(page.getByTestId('order-total')).toContainText('59.46');
    await expect(page.getByTestId('order-confirmation')).toBeVisible();
  });

  test('rejects checkout when stock is insufficient', async ({ page, customer, catalog, request }) => {
    const scarce = catalog.find(p => p.stock === 1);
    const order = orderFactory({ lines: [{ sku: scarce.sku, quantity: 5, unit_cents: 1999 }] });
    const res = await request.post('/api/orders', {
      data: { user: userFactory({ email: customer.email }), order },
    });
    await page.goto(`/checkout/${res.json().id}`);
    await expect(page.getByTestId('error-stock')).toContainText('not enough stock');
  });
});
Neither test depends on the other's data: each creates its own customer through a per-test fixture, reaches the catalogue via a worker-scoped fixture, and hard-codes only the tax and stock boundaries that are the real business rules.
Test Data in the CI/CD Pipeline
| Setup | Isolation | Speed | Best for |
|---|---|---|---|
| Shared staging DB + named scenarios | Low | Fast | Small teams, functional suites |
| Schema-per-worker database | High | Fast | Parallel suites on one Postgres instance |
| Ephemeral environment per run | Total | Slower | Contract, integration and performance suites |
# .github/workflows/test.yml (excerpt)
steps:
  - run: npx prisma migrate deploy          # schema first
  - run: npm run seed:reference            # reference data, idempotent
  - run: npx playwright test --workers=4    # scenarios self-seed per test
  - if: failure()
    run: npm run dump:diagnostics           # export only the failing rows
That last step matters: on failure, extract the rows the failing test touched into a snapshot artifact so the next engineer reproduces locally with DB_URL=./artifact.db.
Common Pitfalls and How to Avoid Them
- The shared mutable staging database. Fix: schema-per-worker or per-branch databases, created on demand and dropped on completion.
- Unseeded randomness. A failure reproduces once in fifty runs. Fix: seed every generator from an env var and log it on failure.
- Fixtures of record width. A 200-field
user.jsonevery test edits. Fix: a small baseline JSON plus override patches. - Copy-paste user objects. 300 near-identical blocks that drift apart. Fix: factories with traits and a lint rule.
- PII in test repositories. A payload pasted from a support ticket. Fix: pre-commit scanning and fixtures in named synthetic-data files.
- No cleanup contract. Rows accumulate until something depends on them. Fix: explicit teardown plus a periodic baseline assertion.
- Impossible data. Names longer than the column, negative quantities, year-9999 timestamps. Fix: take the shape from the schema, then overdrive only the boundaries you care about.
Key Takeaways
- Test data is the real cost centre of automation; design it with the same rigour as test code.
- Healthy data is deterministic, identifiable, isolated and referentially complete.
- Use the simplest pattern that works: literals for boundaries, builders for related fields, factories for volume, fixtures for lifecycle and scope.
- Seed every generator and log the seed. Reproducibility is the cheapest debugging tool you will ever adopt.
- Keep reference data in migrations and scenario data in idempotent seeders; the split makes resets cheap.
- Treat production-derived data as a compliance risk: subset, tokenise deterministically, confirm the legal basis.
Frequently Asked Questions
Should I use random data or fixed data for automated tests? Fixed, wherever the value is part of the assertion, because random values make failures irreproducible. Random-but-seeded data is valuable for volume tests and for property-based generators hunting edge cases. The distinction is intent, not tooling.
How do I keep tests independent when they need the same reference data? Give read-only reference data a wider scope (session or worker) and keep it immutable during a run; give mutable data per-test scope with explicit teardown. Independence is about mutation, not about how many tests read the same currency table.
Is a JSON file better than a factory for complex objects? A hybrid. Keep a small reviewed JSON baseline for the stable shape — it diffs cleanly and documents the contract — and layer a factory or trait system on top for the parts that vary. All-JSON goes brittle as the object grows; all-code loses reviewability.
How do we get production-like data without copying production data? Reconstruct the statistics rather than the content: row counts, field lengths, nullability, referential depth, date distributions. Generate synthetic rows matching those statistics with a seeded generator, and drop the personal data entirely.
Related Articles
- Synthetic Monitoring Explained: Proactively Testing User Journeys Before Your Users Find the Bugs
- Flaky Tests Explained: A Practical Guide to Finding and Eliminating Test Unreliability
- Property-Based Testing Explained: Finding Bugs Your Example-Based Tests Will Never Catch
- Contract Testing Explained: Consumer-Driven Contracts for Microservices
- Playwright Core Methods & Commands: A Complete Test Automation Cheat Sheet


Comments
Post a Comment