Temporal Workflows and Durable Execution for Reliable Applications
A single API request often looks simple from the outside, but the work behind it may cross a database, a payment provider, an inventory service, an email provider, and a human approval process. If the process crashes after charging a customer but before recording the result, a conventional retry can create a second charge. If a workflow waits three days for a warehouse, keeping it in an in-memory task is not realistic.
Temporal is a durable execution platform for these kinds of business processes. Instead of relying on a worker process to stay alive, it records workflow events and replays deterministic workflow code to reconstruct progress. This makes timeouts, process restarts, deployments, and partial failures ordinary cases to handle rather than reasons to rebuild the entire business process from scratch.
This guide focuses on the programming model: what workflows and activities are, how signals and timers fit together, how to make side effects safe, and what teams should consider before adopting Temporal.
Table of Contents
- Why ordinary retries fail
- The durable execution model
- Workflows, activities, and signals
- A complete order workflow
- Determinism, versioning, and deploys
- Operating Temporal in production
- When Temporal is and is not a fit
- Key Takeaways
- Frequently Asked Questions
Why ordinary retries fail
Consider a request handler that creates an order, charges a card, reserves stock, and sends a confirmation email:
async function placeOrder(request: OrderRequest) {
  const order = await orders.create(request);
  await payments.charge(order.id, request.total);
  await inventory.reserve(order.id, request.items);
  await email.sendConfirmation(order.email, order.id);
  return order;
}
A network timeout does not tell the handler whether the payment provider completed the charge. Retrying the entire function can repeat a successful side effect. Moving the steps to a background job does not solve the problem: the job can still fail between two database updates, and its progress may disappear when a worker restarts.
A distributed system also has unavoidable ambiguity. A message can be delayed, a connection can break after a request is accepted, and a dependency can be unavailable for minutes or hours. Reliable software needs a way to remember intent, distinguish completed work from pending work, and resume from the correct point.
Durable execution addresses that gap. The workflow records decisions such as “charge this order” and “wait until Friday.” Activities perform the actual external calls. Temporal persists the resulting events, so a replacement worker can continue the process even if the original process no longer exists.
The durable execution model
Temporal separates orchestration from side effects. That separation is the most important idea to understand.
A workflow is a durable function that makes decisions. It can schedule activities, create timers, receive signals, start child workflows, and wait for other events. It should be deterministic because Temporal may execute it many times while reconstructing the same logical state.
An activity is a unit of work that interacts with the outside world: a database, an API, a message broker, a file system, or a payment gateway. Activities have explicit timeouts and retry policies. Temporal can schedule them again after a worker failure, network error, or temporary dependency outage.
A worker hosts workflow and activity workers. It polls a task queue, executes code, and returns results. The worker is replaceable; the workflow's durable state is not tied to that process.
The flow looks like this:
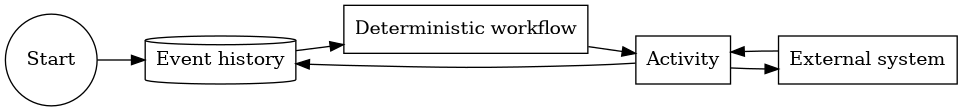
The event history is the durable record. It contains facts such as an activity having started, an activity having completed, a timer having fired, or a signal having arrived. On a new worker, Temporal replays those events through the workflow code. The code reaches the same decision points and continues from the next unfinished operation.
This is different from simply storing a status column. A status can tell you that an order is pending, but it does not automatically reconstruct which timer is outstanding, which activity needs retrying, or which external operation may already have succeeded. The event history preserves the decision trail.
| Concern | Conventional handler | Durable workflow |
|---|---|---|
| Process crash | Progress held in memory is lost | History reconstructs the next decision |
| Long wait | A worker or thread must remain alive | A timer remains durable |
| External failure | The whole handler is often retried | The failed activity is retried independently |
| Auditability | Logs must be assembled separately | Events form a decision history |
| Deployment | In-flight work may be interrupted | Work replays under compatible code |
Durable execution guarantees that workflow progress can be reconstructed. It does not magically make an arbitrary third-party API exactly-once. Activities need idempotency, careful error classification, and sometimes reconciliation.
Workflows, activities, and signals
A useful design rule is: put business decisions in workflows and external effects in activities. The workflow should read like a process description, while activity implementations should look like ordinary, testable service functions.
Workflows
A workflow can:
- Call another workflow as a child or standalone workflow.
- Execute activities with a timeout and retry policy.
- Create durable timers instead of sleeping a process thread.
- Wait for signals or updates from users and other systems.
- Return a result or enter a terminal failure or cancellation state.
Workflow code can be long-running without keeping a thread or container alive. A timer for “check again in six hours” is an event scheduled in Temporal, not an open promise held by a server process.
Activities
An activity is where non-deterministic work belongs. Typical examples include:
- Inserting an order into a database
- Calling a payment provider
- Publishing a message to Kafka
- Generating a PDF
- Sending an email
- Reading or writing a file through a controlled service
Activity retries are not automatically safe for every operation. Give each activity an idempotency key derived from a stable business identifier, usually the workflow or order ID. If a payment provider supports idempotency keys, pass the same key on every retry. If it does not, record the provider request and result in your own durable ledger before deciding how to recover from an ambiguous timeout.
Timeouts and retries should reflect the dependency rather than use one global policy. A short inventory lookup might have a five-second start-to-close timeout. A document conversion might need a heartbeat and a much longer execution window. Retriable errors such as rate limits or temporary connection failures can be retried; validation errors and business rejections usually should be returned as non-retryable failures.
Signals, queries, and updates
A signal delivers information to a running workflow. A shipment system might signal that an item was dispatched, or a customer might signal approval. Signals are useful when the next step depends on an event that did not exist when the workflow started.
A query reads workflow state without changing it. A support dashboard might query the current fulfillment stage. An update is intended to request a state change and can return a result; it is a better fit than a signal when the caller needs validation or an immediate acknowledgement. The exact update-handler API varies by SDK, but the conceptual distinction remains: queries observe, signals notify, and updates request a change.
A complete order workflow
Imagine an order that must reserve inventory, collect payment, wait for fulfillment, and create a shipment. The workflow below is illustrative TypeScript using the Temporal SDK. Its purpose is to show the separation of concerns, not to replace the SDK's version-specific setup.
import { proxyActivities, sleep } from "@temporalio/workflow";

type Order = {
  id: string;
  email: string;
  totalCents: number;
  items: string[];
};

type OrderActivities = {
  reserveInventory(orderId: string, items: string[]): Promise<{ reservationId: string }>;
  releaseInventory(reservationId: string): Promise<void>;
  chargePayment(orderId: string, amountCents: number, reservationId: string): Promise<{ status: string }>;
  notifyCustomer(orderId: string, message: string): Promise<void>;
  createShipment(orderId: string, reservationId: string): Promise<{ trackingId: string }>;
};

export async function fulfillOrder(order: Order): Promise<string> {
  const activities = proxyActivities<OrderActivities>({
    startToCloseTimeout: "30 seconds",
    retry: {
      maximumAttempts: 5,
      backoffCoefficient: 2,
    },
  });

  const reservation = await activities.reserveInventory(order.id, order.items);
  const payment = await activities.chargePayment(
    order.id,
    order.totalCents,
    reservation.reservationId,
  );

  if (payment.status === "declined") {
    await activities.releaseInventory(reservation.reservationId);
    return "declined";
  }

  await activities.notifyCustomer(order.id, "Payment accepted");
  await sleep("2 days");

  const shipment = await activities.createShipment(order.id, reservation.reservationId);
  return shipment.trackingId;
}
The workflow remains readable because each line represents a durable decision. If chargePayment times out after the provider accepted the request, Temporal can retry the activity. The payment implementation should use order.id as its provider idempotency key so a retry cannot create a second charge.
The timeout after payment is equally important. The process can disappear during the two-day wait, but the timer and the next activity are already represented in event history. A new worker can replay the workflow and continue waiting from the correct point.
For a more interactive process, define a signal such as shipment_ready and wait for either that signal or a cancellation request. The workflow can then choose a shipment activity based on the signal payload. Keep the signal payload small and stable; the durable history is not a substitute for a full event-streaming platform.
Designing safe compensation
Failure recovery is not always a simple retry. If payment succeeds and shipment creation fails permanently, the business may need to refund the customer and release inventory. Model compensation as explicit workflow decisions rather than hiding it in a catch block.
A useful activity contract can make the safe key visible:
export async function chargePayment(orderId: string, amountCents: number) {
  return paymentGateway.charge({
    amountCents,
    idempotencyKey: `order:${orderId}`,
  });
}
Compensation itself can fail, so it should also be an activity with its own retry policy and business-level idempotency. A workflow is durable, but your real-world invariants still require explicit application logic.
Determinism, versioning, and deploys
Temporal replays workflow code against old events. That gives deployments a strict compatibility requirement: the code must make the same decisions for the same history.
The following operations are poor choices inside workflow code:
- Calling
Date.now()to decide whether a deadline passed - Generating a random ID
- Reading an environment variable that changes between runs
- Querying a database or HTTP API
- Depending on unordered map or set iteration when it affects the next command
- Calling a random-number generator to choose a business path
Use workflow time, deterministic identifiers, and activities for those values. For example, a durable timer can establish a deadline, and an activity can generate a UUID that is then recorded in history.
Deploying changed workflow code does not automatically erase the meaning of an existing history. Temporal may execute the new code against events written by the previous version. That is why workflow code should be treated as a long-lived data format, not as disposable request-handler code.
Safe change practices
- Prefer additive changes. Add a new activity or branch after a known state rather than rewriting the interpretation of old events.
- Use the SDK's patching or versioning facilities. They let old histories replay under a compatible code path while new executions use the new behavior.
- Version external payloads. A signal or update payload should have a documented shape and a migration strategy.
- Test replay against production-shaped histories. A unit test that starts a fresh workflow cannot detect many nondeterminism problems.
- Avoid changing retry semantics without understanding history. An already recorded command is not retroactively replaced just because the worker configuration changed.
A nondeterminism error should be treated as a deployment signal, not suppressed with a broad catch. It means that the code and the recorded decisions disagree.
Operating Temporal in production
Temporal removes some failure-handling code, but it does not remove operational responsibility. The following practices make durable workflows easier to reason about.
Model around business boundaries
Create a workflow for a meaningful, resumable process such as order fulfillment, subscription provisioning, or document approval. Do not wrap every database query in a workflow. If a process is a single short operation with no meaningful intermediate state, a normal service call may be simpler and cheaper.
Make activities idempotent and observable
Use stable business keys, record ambiguous external calls, and emit metrics or traces from both workflow and activity code. A useful activity dashboard can answer:
- Which activity types have the highest failure rate?
- How long do retries and timeouts take?
- Which external dependencies are producing ambiguous responses?
- How many workflows are waiting on a signal or timer?
Temporal provides visibility primitives and metrics, but application-level identifiers still matter. Put an order ID or request ID in logs and searchable attributes without copying unnecessary personal data into the event history.
Isolate queues and control capacity
Task queues let teams separate environments, workloads, or traffic classes. Isolating a noisy activity from a latency-sensitive workflow prevents one dependency from exhausting every worker. Size workers from observed task concurrency, activity duration, and downstream limits rather than from CPU alone.
Protect sensitive data
Event history is durable and may be inspected by operators, workers, and debugging tools. Do not put passwords, access tokens, or unnecessary payment details in workflow inputs, signals, or activity results. Store references to secrets and retrieve short-lived credentials inside activities, using the platform's supported encryption and access controls.
Treat workflow history as a long-lived audit log, not as a convenient place to stash every value your process happens to have in memory.
Plan for long histories
A workflow that loops indefinitely can accumulate many events even when each iteration is individually small. Use Continue-As-New to start a fresh run with a linked history when a long-lived workflow naturally reaches a checkpoint, and use archival or retention policies for completed workflows. Choose a checkpoint based on business boundaries, such as a completed billing month, rather than an arbitrary event count.
Test failure paths
Useful tests include replay tests, activity unit tests with an in-memory or test double, and integration tests that exercise a real test server or namespace. Simulate a worker disappearing between activities, a dependency returning a retryable error, a non-retryable rejection, and a signal arriving after a deployment. Durable execution is most valuable when the failure cases are designed before production.
When Temporal is and is not a fit
Temporal is a strong candidate when a business process has several of these characteristics:
- It spans multiple services or external providers.
- It must survive process restarts and deployments.
- It includes timers, callbacks, or human approval.
- Retrying the whole operation could duplicate a side effect.
- The team needs a durable record of progress and decisions.
It may be unnecessary for a simple CRUD endpoint, a short-lived background job, or a pure computation. A conventional queue with idempotent consumers can be a better fit when the job has one clear unit of work and no long-lived process state. A database-backed state machine can also solve a narrower problem with less operational overhead.
The right comparison is not “workflow engine versus no workflow engine.” Compare the cost of implementing recovery, timers, auditability, and coordination yourself with the value Temporal provides. A small service may not need that machinery; an order, onboarding, or claims system often does.
Temporal is also not a replacement for every other platform. You still need a database for application data, a queue or event bus for high-volume messaging, and an observability system for operational insight. Temporal coordinates a process; it does not eliminate the systems that process participates in.
Key Takeaways
- Durable execution stores workflow progress as events, so a new worker can resume after crashes or deployments.
- Keep deterministic business decisions in workflows and put network, database, and file-system side effects in activities.
- Use timeouts, retry classification, idempotency keys, and explicit compensation rather than assuming a retry is harmless.
- Signals, queries, updates, and durable timers make long-running and human-in-the-loop processes first-class.
- Treat workflow code as versioned history: use replay tests, SDK patching, payload migrations, and careful deployment practices.
- Start with processes that genuinely need recovery; do not turn every request into a workflow.
Frequently Asked Questions
Is Temporal exactly-once execution?
No. Temporal provides durable workflow execution and can retry activities, but external systems may observe repeated requests. Use idempotency keys and application-level safeguards for payments, messages, and other side effects.
What is the difference between a workflow and an activity?
A workflow makes deterministic orchestration decisions and records progress. An activity performs external work, has a timeout and retry policy, and should be designed to tolerate duplicate execution.
Can a workflow wait for days or months?
Yes. Use a Temporal timer rather than keeping a process or thread waiting. The workflow can remain suspended until the timer fires, a signal arrives, or another event occurs.
What happens when workflow code changes during a deployment?
Existing workflows may replay old events through the new code. Keep changes compatible with prior history, test replay, and use the SDK's patching or versioning mechanisms when behavior must diverge.
Should secrets be stored in workflow inputs?
No. Keep workflow payloads and history limited to the data needed for the process. Resolve secrets inside activities through approved secret management and avoid putting long-lived credentials into durable history.


Comments
Post a Comment